 تخطي إلى المحتوى




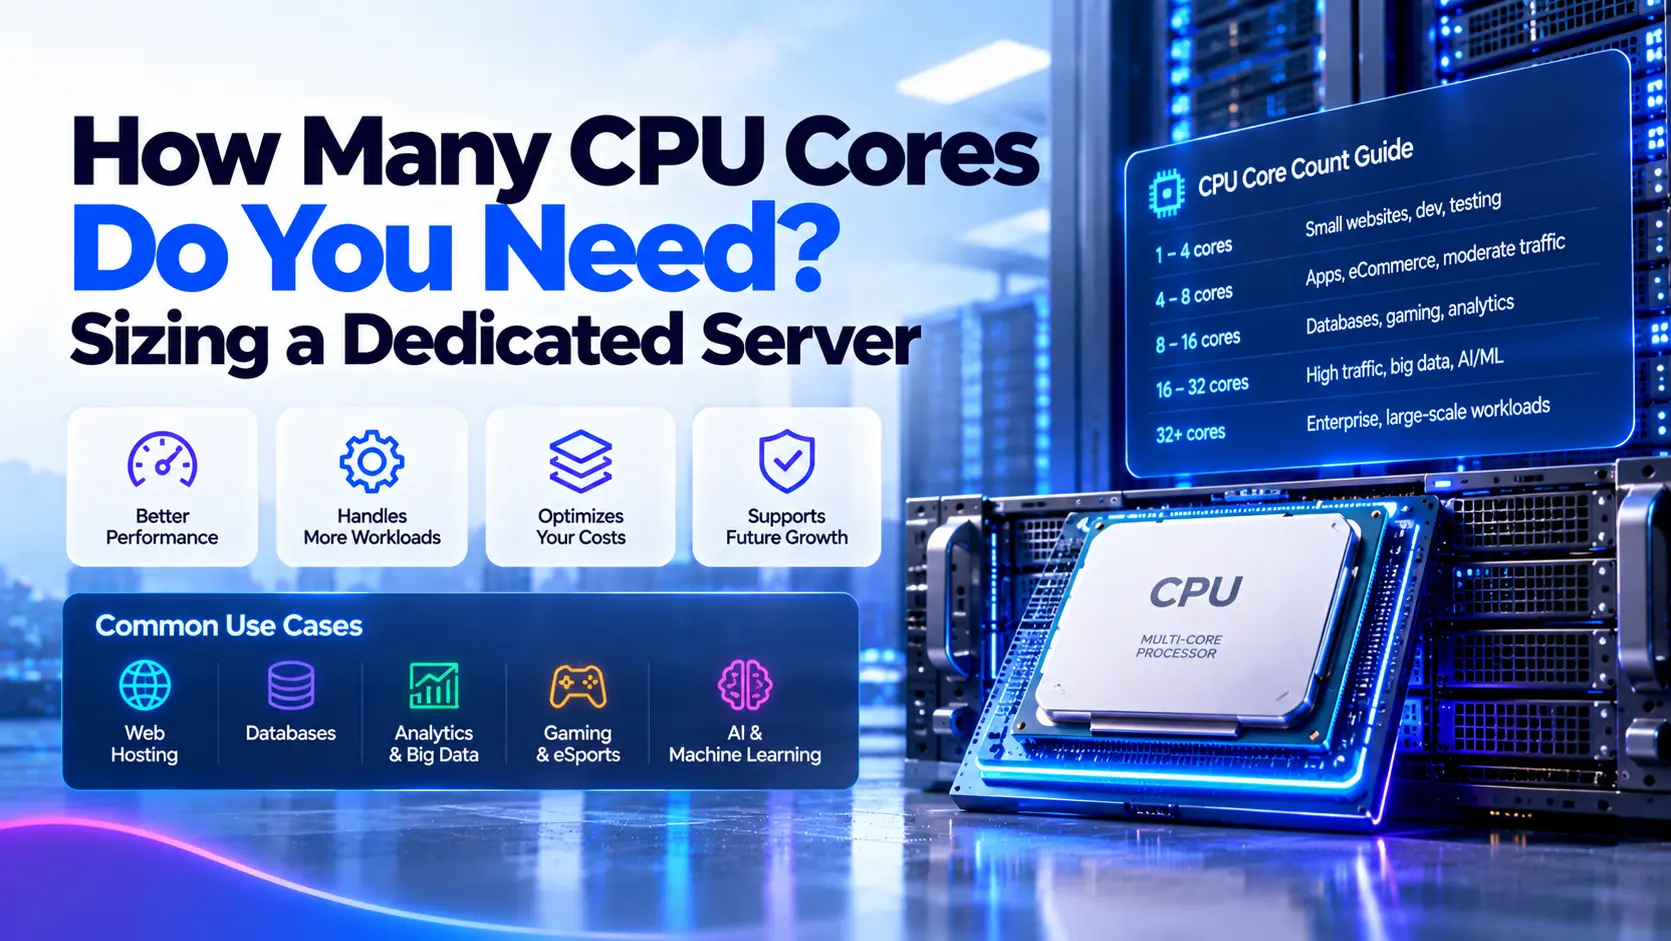
A small web application may run well on four CPU cores. A busy database or virtualization host may need sixteen, thirty-two, or more. The right number depends on how much processing your workload requires, how much work can run in parallel, and how quickly each core completes that work.
Choose a dedicated server by measuring peak CPU demand, checking application response times, and testing a configuration with spare capacity. Core count alone cannot tell you whether a server will meet your needs.
In this guide, we explain how to make that estimate, identify other performance limits, and choose a configuration you can justify.
How Many CPU Cores Does a Dedicated Server Need?
Use core-count ranges to build a shortlist, then test against your actual workload. The following ranges are planning suggestions for initial tests, not minimum requirements or promised capacity.
| Workload | Initial physical core count to consider | What changes the requirement |
| Small website or lightweight application | 4–8 | Dynamic requests, caching, background tasks |
| Growing web application or API | 8–16 | Request rate, CPU time per request, response-time target |
| Database server | 8–16 initially | Query complexity, active queries, memory, storage |
| One or a few game-server instances | 4–8 with strong per-core performance | Game engine, settings, plugins, active world |
| Small virtualization host | 8–16 | Combined VM demand, host services, memory capacity |
| Larger VM host or parallel processing service | 16–32+ | Active jobs, contention, workload distribution |
| Build workers or CPU-based encoding | 8–32+ | Parallel tasks, job deadlines, memory bandwidth |
These ranges overlap because applications behave differently. An efficient service can handle more work on fewer cores than an application that performs expensive processing for every request.
We recommend treating the table as a starting point for measurement. A four-core server may be sufficient, while a thirty-two-core server may still struggle with a single slow application thread.
Visitor Counts Do Not Establish CPU Requirements
Monthly visitors tell you little about the work a server performs at its busiest moment.
Consider two websites with the same traffic:
- One serves cached pages through a content delivery network.
- The other generates personalized pages, checks inventory, and runs database queries for each visit.
Their origin servers can have very different CPU requirements.
Measure requests reaching the server, the work performed per request, and the busiest periods. For background processing, measure jobs per second and CPU time per job.
If you are moving from shared hosting, first confirm which resources your current plan limits. Our explanation of استضافة خادم مخصص covers the basic hosting model.
Understand Cores, Threads, Sockets, and vCPUs
A physical core is a processing unit within a CPU. A socket holds a physical processor. Hardware threads expose additional logical processors that share a core’s resources.
These numbers describe the hardware, but they do not represent interchangeable units of performance.
| Term | Meaning | Sizing implication |
| CPU socket | Position for an installed processor | Count the cores across installed processors |
| Physical core | Processing unit within a CPU | Useful starting point for hardware comparisons |
| Hardware thread | Logical processor sharing a physical core | Does not provide another full physical core |
| Software thread | Sequence of application instructions | May run, wait, or compete for CPU time |
| vCPU | Processor presented to a virtual machine | Its performance depends on the host and allocation |
For a hypothetical server with two processors, eight cores per processor, and two hardware threads per core:
Physical cores = 2 × 8 = 16
Logical processors = 16 × 2 = 32
That server has sixteen physical cores, not thirty-two.
Hardware Threads Do Not Double CPU Capacity
SMT, including Intel Hyper-Threading on supported processors, lets multiple hardware threads share a physical core.
The performance benefit depends on the application and the resources it uses. Do not assume that enabling SMT doubles throughput or provides a fixed percentage gain.
Test the production workload with the intended configuration.
vCPUs Cannot Be Converted With One Universal Ratio
A sixteen-vCPU cloud instance does not automatically match a sixteen-core dedicated server.
AWS documents different relationships between vCPUs, physical cores, and threads across instance types. CPU generation, host sharing, and sustained performance also affect the comparison.
When moving from a VM to dedicated hardware, use the existing system to measure workload behavior. Then test the destination CPU rather than converting the advertised counts directly.
When Do Faster Cores Matter More Than More Cores?
Faster cores matter when a task depends on a sequence of work that cannot spread across many cores. Additional cores help when the application has enough independent work to keep them busy.
A web service may process many requests in parallel while each individual request follows a mostly serial path. It needs both sufficient total capacity and adequate performance per core.
One Busy Thread Can Hide Behind Low Overall CPU Use
Consider an eight-core server with SMT disabled. One application thread fully occupies one core while the other cores are mostly idle.
The server may report roughly 12.5% overall CPU utilization. Yet that thread has no spare processing capacity.
Adding eight more cores may leave the slow operation unchanged. The next step is to inspect the application, its serial work, and the performance of the individual core.
This pattern can occur in game loops, application workers, and parts of database execution.
More Cores Help Independent Work
Additional cores can support more:
- Independent application requests.
- Background workers.
- Virtual machines with active workloads.
- Parallel build tasks.
- Encoding or processing jobs.
The benefit stops growing at the same rate when another resource becomes the limit. Memory bandwidth, shared locks, storage, and application design can all restrict scaling.
Compare Exact Processor Models
Do not choose between servers using core count and GHz alone.
Compare processor generation, sustained performance, cache behavior, memory support, and tests that resemble your workload. A newer processor with fewer cores may complete more useful work than an older processor with a larger core count.
For larger systems, also consider NUMA. This describes a memory layout where access costs depend on which processor or node owns the memory. Poor placement can affect VM and application performance.
Measure Your Current Server Before Choosing a Core Count
Collect CPU data alongside application performance. A server that stays responsive at high CPU use has a different capacity problem from one that misses response-time targets at moderate use.
Record at least one representative business cycle. Include busy periods, scheduled jobs, backups, imports, and reporting tasks. Use longer records if weekly or seasonal events change demand.
Check the CPU Configuration
On Linux, run:
lscpu
Review the model name, sockets, cores per socket, threads per core, and online logical processors.
Inside a VM, the displayed topology usually describes the guest configuration. It may differ from the physical host.
Inspect Activity by Logical Processor
Use:
mpstat -P ALL 1 10
This produces ten reports at one-second intervals for the available logical processors. Look for uneven activity and sustained CPU work. The command belongs to the sysstat package.
A short sample helps inspect a current problem. It does not replace historical monitoring.
Identify Busy Processes and Threads
Use:
pidstat -u 1 10
For thread-level detail:
pidstat -u -t 1 10
pidstat also belongs to sysstat. Its reporting options affect how CPU percentages are presented. Check whether your monitoring tool treats 100% as one logical processor or the entire system before comparing figures.
Check Runnable Work and Resource Pressure
Run:
vmstat 1 10
Review runnable tasks, CPU activity, and memory behavior. The first report generally covers activity since boot; later reports cover the sampling interval.
On systems with Linux Pressure Stall Information enabled, also inspect:
cat /proc/pressure/cpu
cat /proc/pressure/memory
cat /proc/pressure/io
The CPU some measurement reports time during which at least some tasks wait for CPU resources. Use it alongside application latency and other metrics.
Do not interpret load average as CPU utilization. Linux load average includes runnable tasks and tasks in uninterruptible sleep, often associated with I/O.
Record What Users Experience
Track these measurements over the same period:
| Measurement | What it tells you |
| Requests or jobs completed per second | Useful work completed |
| p95 and p99 response time | How slower requests behave |
| Error and timeout rate | Whether work fails under load |
| Queue length and job age | Whether unfinished work accumulates |
| CPU activity and pressure | Whether processing demand is competing for time |
| Memory and storage behavior | Whether another resource limits progress |
A p95 response time is the value at or below which 95% of measured requests finish. It helps show delays that an average can hide.
Calculate an Initial CPU Capacity Estimate
A useful estimate starts with CPU time consumed during a representative interval.
CPU time records time spent executing work. It differs from elapsed time, which can include waiting for a database, disk, network response, or lock.
Method 1: Use Measured CPU Time
Calculate:
CPU demand = CPU-seconds consumed ÷ elapsed seconds
Then apply growth and an operating target:
Initial capacity estimate =
CPU demand × growth factor ÷ target utilization
Use utilization as a decimal. For example, 65% becomes 0.65.
The following calculation assumes comparable physical cores, SMT disabled, enough parallel work, and no other limiting resource. It is an illustrative example, not a measured Atal Networks result.
| Input | Example value |
| CPU time consumed | 240 CPU-seconds |
| Measurement interval | 60 seconds |
| Planned workload growth | 25% |
| Target utilization | 65% |
First calculate current demand:
240 ÷ 60 = 4 CPU-seconds per second
Then add growth and operating room:
4 × 1.25 ÷ 0.65 = 7.69
Round up to an eight-core test configuration.
The 65% target is a chosen planning assumption. It is not a universal operating limit. A service with strict response-time requirements may need more spare capacity. A batch system may tolerate longer queues and higher utilization.
This estimate becomes unreliable if the source server is already saturated. Completed CPU work cannot reveal all unmet demand. A growing request queue or rising timeout rate means you need load tests or another way to estimate the missing work.
Method 2: Use Requests and CPU Time per Request
For a request-driven workload:
CPU demand =
requests per second × CPU-seconds per request
Suppose an application processes 200 requests per second. Each request consumes an average of 15 milliseconds of CPU time:
200 × 0.015 = 3 CPU-seconds per second
If separate background work consumes another 0.5 CPU-seconds per second, total measured demand becomes 3.5.
Include that background work only if it was excluded from the request measurement.
Use a representative traffic mix. Login requests, searches, reports, and cached responses may have very different CPU costs.
Keep the Estimate Within Its Limits
These formulas provide test candidates, not guaranteed purchasing answers.
Recheck the result when:
- The destination CPU differs from the source.
- SMT settings change.
- Request types or payload sizes change.
- Cache behavior changes.
- The application cannot use additional cores.
- Memory or storage already limits performance.
Scheduler time on SMT threads does not translate directly into equivalent physical-core performance. Test the exact target configuration when that distinction affects the decision.
Adjust CPU Sizing for Your Workload
The calculation gives you a baseline. Application behavior determines whether that baseline is useful.
Websites, WordPress, and APIs
Separate cached traffic from requests that reach application workers.
For WordPress, inspect uncached pages, searches, admin activity, checkout requests, and scheduled tasks. For APIs, measure endpoints separately before calculating a weighted average.
Worker count also matters. Too few workers can leave CPU capacity unused. Too many can create memory pressure or overload the database.
Increase worker limits through testing, with CPU, RAM, and database behavior recorded at each step.
MySQL and PostgreSQL Databases
Database CPU requirements depend on active queries and the work they perform.
Check query plans, indexes, lock waits, and storage delays before adding cores. A query that scans unnecessary rows can consume more CPU than a correctly indexed query serving the same request.
Memory matters because frequently accessed data may need to stay in RAM. Storage matters when queries wait for reads or writes.
Some database workloads benefit from strong per-core performance. Others can use substantial parallel capacity. The label “database server” alone does not identify which applies.
Minecraft and Other Game Servers
For game hosting, check the performance of the main simulation work as well as total CPU use.
A single instance may reach a thread limit while the server still has idle cores. Several independent instances can use more of the machine.
Game version, plugins, mods, world activity, and server settings all affect demand. There is no dependable player-per-core rule that applies across games.
Match the CPU to measure game performance before comparing dedicated game server options.
Proxmox, Virtual Machines, and Containers
A total of forty allocated vCPUs does not mean the host needs forty physical cores. It also does not prove that a smaller host will perform well.
Measure the guests’ combined activity during overlapping busy periods. Include host services, storage work, backups, and migration tasks.
For containers, check CPU quotas. Linux cgroup controls can limit CPU time even when the host has spare capacity. Review throttling statistics before buying more hardware.
Avoid fixed VM-per-core ratios. Ten mostly idle VMs and ten CPU-heavy VMs create different requirements.
Build Jobs, Encoding, and AI Services
Parallel jobs can use many cores, but memory and storage must keep pace.
For build systems, measure completion time at different job counts. For encoding, confirm whether the work uses the CPU or a hardware encoder.
For AI services, distinguish CPU-only inference from workloads that use GPUs. CPU preprocessing, memory bandwidth, accelerator access, and request concurrency can each become the limit.
Choose capacity from the actual processing path rather than assigning a fixed number of cores to each GPU.
Check Whether CPU Is the Real Bottleneck
Adding cores helps when usable CPU capacity limits the work. It will not automatically fix storage delays, lock contention, or application limits.
| Observed condition | Investigate first | Possible response |
| One thread stays busy while other CPUs have capacity | Serial code, locks, per-core performance | Tune the application or test a faster core |
| Many CPUs stay busy and runnable work grows | CPU demand and application efficiency | Add capacity or reduce CPU cost |
| Low CPU use with high storage latency | Queries, storage path, I/O pattern | Improve storage or reduce I/O |
| Memory pressure with active swapping | Working set and RAM allocation | Add RAM or reduce memory demand |
| Container throttling with idle host capacity | CPU quota and scheduling controls | Adjust limits where appropriate |
| Long database lock waits | Transaction length and lock behavior | Change queries or transaction design |
| Network throughput reaches a ceiling | Port capacity, packet processing, network path | Address the network limit |
Treat these as investigation paths. Confirm the cause using several measurements.
Moving a workload from sixteen to thirty-two cores can increase cost while leaving response time unchanged if the workload still waits on the same disk or lock.
Plan Spare Capacity, Growth, and Failover
Spare CPU capacity supports bursts and workload changes. The amount you need depends on service targets and how quickly you can add capacity.
Separate Growth From Operating Headroom
Growth describes additional work you expect.
Headroom describes unused capacity you retain at the planned workload.
If your calculation already divides by a target utilization, it already includes operating headroom. Do not add another percentage for the same purpose without explaining the reason.
Include background jobs separately only when the original measurement excluded them.
Size Surviving Servers for Failover
Suppose two comparable servers normally share traffic evenly. Each operates at 35% CPU during the planned peak.
If one fails, the remaining server could approach 70% under a simple proportional estimate. Replication, recovery, and changed cache behavior may add more work.
Test the failure condition, not just normal operation.
Two processors in one server do not provide server-level failover. A second server is a separate availability decision. AMD’s server guidance makes this distinction between processor count and failover capacity.
Decide Whether to Add Cores or Another Server
A larger server may suit a workload that benefits from shared memory and a simple deployment.
Additional servers may suit independent application instances, separate game worlds, or worker queues. They can also support availability requirements.
Account for the operational work involved: load balancing, shared state, replication, monitoring, and recovery.
Test the Configuration Before Committing
A load test should answer whether the configuration meets your service targets under expected demand.
Reproduce the Work That Matters
Use representative data, requests, and background tasks.
Include normal cache behavior and relevant recovery conditions. A test that serves only warm cached pages cannot establish capacity for uncached checkout or search traffic.
Run controlled tests in an appropriate environment. Uncontrolled production load can disrupt users.
Increase Load in Steps
At each level, record:
- Completed requests or jobs.
- Response times.
- Errors and timeouts.
- CPU activity and pressure.
- Memory use.
- Storage latency.
- Queue growth.
Run long enough to observe sustained behavior and relevant background tasks. Stop treating a configuration as sufficient when it misses the chosen service targets, even if average CPU use looks acceptable.
Also confirm that the load generator is not the limiting system.
Record the Test Conditions
Keep a short test record:
| Item | Record |
| Hardware | Exact CPU model, physical cores, SMT setting |
| Memory | Capacity and configuration |
| التخزين | Drive type and layout |
| Software | OS, application, database, and runtime versions |
| Workload | Request mix, data size, concurrency |
| Duration | Test length and background tasks included |
| Pass criteria | Latency, errors, throughput, queue limits |
| Result | Highest tested load that met the criteria |
A reproducible result is more useful than a generic CPU benchmark.
Choose a Dedicated Server From the Results
Once the workload passes testing, compare the complete server configuration.
Confirm the exact CPU model and physical core count. Then check RAM, storage, network capacity, and any application-specific requirements.
Include Software Licensing
Some products charge according to physical cores, virtual cores, editions, or deployment rights. Extra cores can therefore change software cost as well as hosting cost.
Check the current terms for your software and hosting arrangement. Do not assume that disabling cores or reducing VM allocations changes the license bill.
Confirm the Upgrade Path
Dedicated-server CPU changes may require compatible hardware, downtime, or migration to another machine.
Before ordering, confirm:
- Which upgrades are available.
- Whether CPU changes require migration.
- How long the change may take.
- How backups and rollbacks will work.
- Whether another server would be a better expansion path.
Atal Networks’ dedicated server configurations provide a place to compare available options. Share your application requirements, peak-load measurements, and test results when discussing a configuration with our team.
We recommend choosing from those requirements rather than selecting the plan with the largest advertised core count.
الأسئلة الشائعة
Is Four Cores Enough for a Dedicated Server?
Four physical cores can be enough for a lightweight application, small website, or limited background workload. The CPU model, caching, and peak demand determine whether it fits. Test the busiest expected period before committing.
Is Eight Cores Enough for a Web Server?
Eight cores can provide a useful starting point for many web applications. Capacity depends on request processing cost, traffic reaching the origin, worker settings, and database behavior. There is no fixed visitor count that eight cores will support.
Does Eight Cores and Sixteen Threads Mean Sixteen Cores?
No. It means eight physical cores expose sixteen hardware threads. Threads sharing one core also share execution resources. They do not provide the same capacity as sixteen independent physical cores.
Can Eight Newer Cores Outperform Sixteen Older Cores?
Yes, depending on the processors and workload. Architecture, performance per core, cache, and memory behavior affect results. Compare exact models using the application you intend to run.
How Many Cores Do I Need for Ten Virtual Machines?
VM count alone cannot answer that question. Measure their combined peak CPU demand, include host work, and check whether their busy periods overlap. Confirm that RAM and storage can support the same workload.
Why Is My Server Slow When CPU Usage Is Low?
A single busy thread, storage delay, database lock, memory pressure, or CPU quota can limit performance. Overall CPU utilization can hide these conditions. Inspect process activity and resource waits alongside response times.
Can I Size a Server From Monthly Visitors?
Monthly visitors are insufficient for CPU sizing. You need peak request rates, the share of traffic reaching the server, and the CPU cost of those requests. Scheduled work also contributes to demand.
Can I Add CPU Cores Later?
Sometimes, but it depends on the physical platform and provider. An upgrade may require a different processor or migration to another server. Confirm the process before renting the original configuration.
Recommended Next Steps
Start with your busiest workload period. Record CPU demand, application response times, memory behavior, and storage delays.
Then:
- Identify whether total CPU capacity or one busy thread limits performance.
- Calculate an initial configuration using clear growth and headroom assumptions.
- Test comparable hardware with representative work.
- Check licensing and migration requirements.
- Choose the configuration that meets your service targets with room to grow.
The right core count is the one that passes your workload test at an acceptable total cost.