 Aller au contenu





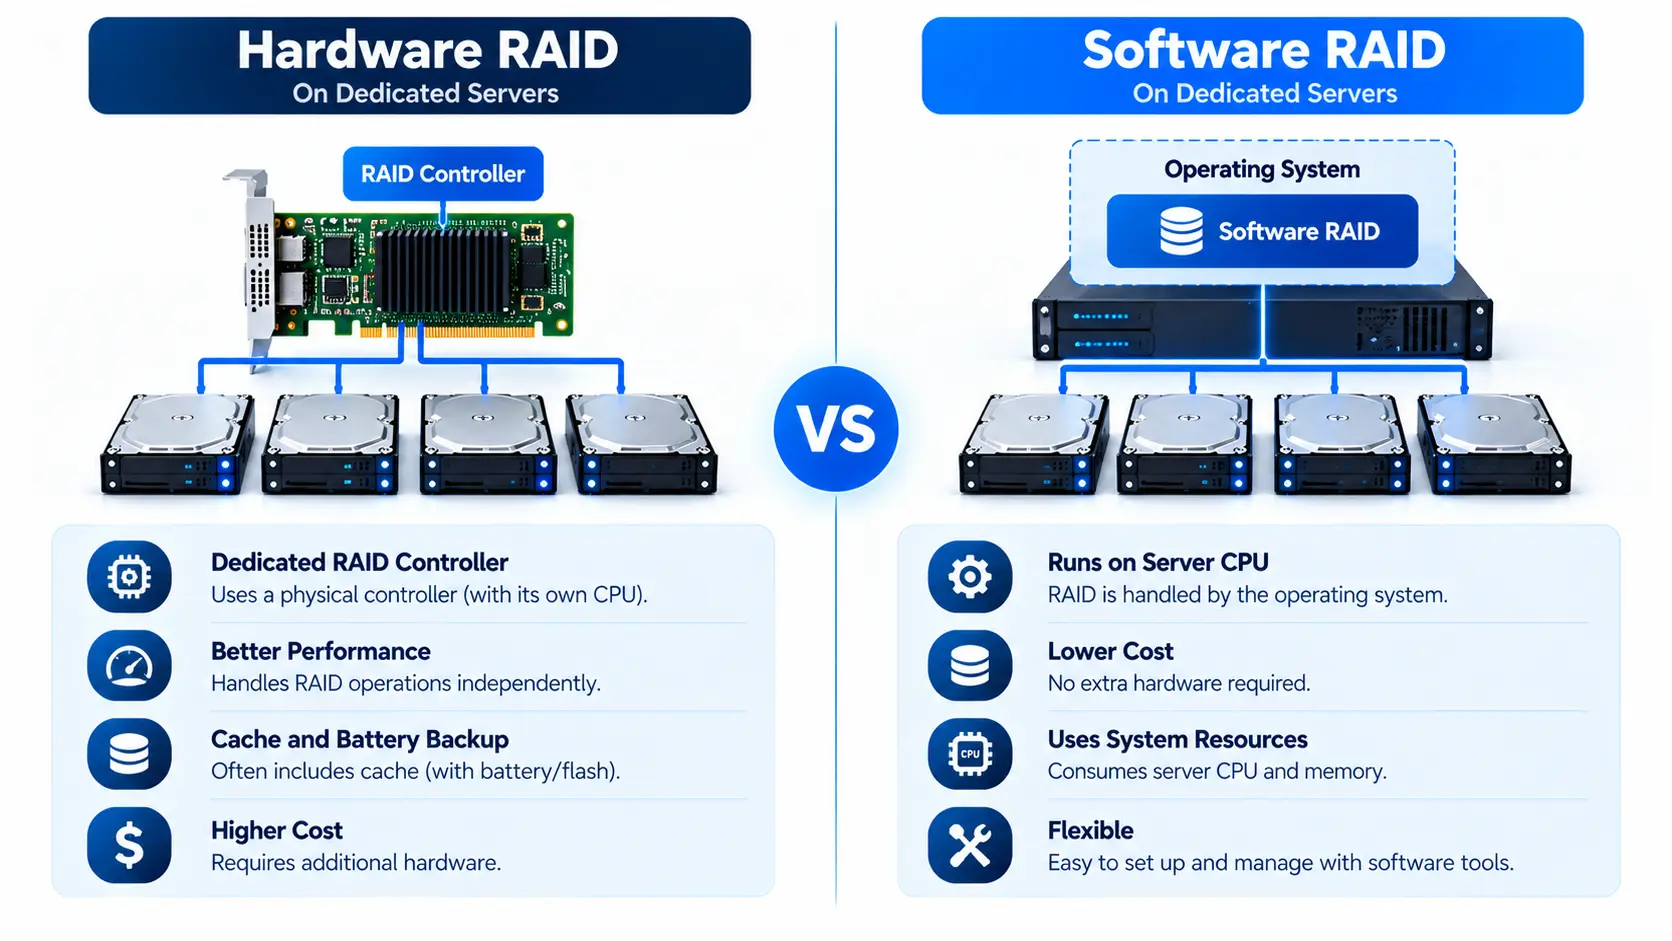
Hardware RAID uses a dedicated controller to manage a disk array. Software RAID uses the server’s operating system, such as Linux MD managed by mdadm. Both can mirror data and keep an array available after a drive fails. The better choice depends on the drives, RAID level, workload, write-cache protection, recovery plan, and support included with the server.
For a two-drive Linux data mirror, software RAID often gives an administrator direct disk visibility without a separate RAID card. A supported hardware controller may suit a fleet that relies on its management tools or a tested workload that benefits from protected write-back cache. Neither choice removes the need for backups.
Hardware RAID vs software RAID at a glance
| Decision point | Hardware RAID | Software RAID with Linux MD |
| Array management | Controller firmware manages the array | Linux kernel manages the array; mdadm configures and monitors it |
| What the OS sees | Usually a controller-created virtual disk; physical-drive detail may require vendor tools | Member drives and the MD array are visible to Linux |
| Processing | Controller performs RAID work, while the host still handles storage I/O | Uses host CPU and memory for RAID work |
| Write cache | Some controllers offer write-back cache with battery or flash protection | Relies on the OS, drive, and filesystem write path; no controller cache is required |
| Controller failure | May require a compatible replacement and array import | No dedicated RAID controller is needed if disks are exposed directly |
| Boot setup | Firmware can boot a supported controller virtual disk | Root array, bootloader, and UEFI or BIOS layout must all work |
| Monitoring | Controller tools, firmware events, and provider integration | MD status, OS alerts, and per-drive health tools |
| Coût | Controller and protection hardware may add cost | May avoid a RAID-card option, but needs OS administration |
These are architectural differences, not a performance ranking. A basic controller without protected cache is not equivalent to a high-end card configured for protected write-back. Linux MD also differs from chipset-assisted RAID marketed through a firmware setup screen. Confirm what hardware and software a dedicated-server plan actually supplies. Red Hat documents MD as a Linux software RAID subsystem.
How each design handles the disks
Hardware RAID presents a controller-managed volume
A RAID controller sits between physical drives and the operating system. It groups selected disks into a virtual disk, handles the RAID layout, and reports status through its firmware or management software. Linux may see one logical device even though several drives sit behind it.
This can make an array straightforward to present to an installer and lets an operations team manage supported controllers with established tools. It also makes the controller part of the recovery plan. If it fails, the team may need a compatible replacement and the vendor’s procedure for importing the existing array. Do not initialize a new array over disks that already hold a foreign configuration.
Not every card labeled RAID has the same capabilities. Check the exact controller, firmware, drive interface, supported RAID levels, cache module, and monitoring tools. An HBA in pass-through or JBOD mode exposes individual drives and serves a different role from a controller that presents one RAID virtual disk.
Software RAID keeps array management in Linux
Linux MD combines block devices using metadata on the array members. The administrator creates and monitors arrays with mdadm; the filesystem sits above the MD device. On a server with direct disk access, Linux can identify individual members and inspect their health alongside array status.
There is no separate RAID card whose firmware must interpret the array. That can make a move to suitable replacement hardware less dependent on a particular controller model. Recovery still needs intact drives and metadata, compatible Linux support, correct assembly, and a working boot path if the operating system lives on the array. It is not a promise that any set of disks will start on any server.
Our companion guide to setting up an mdadm RAID 1 data mirror can be linked here once it has a public URL.
Firmware RAID and ZFS are separate choices
Motherboard or platform firmware can advertise RAID without supplying a dedicated controller that performs all RAID work. Its driver, boot support, and licensing may differ from both a standalone controller and Linux MD. Ask the provider which implementation is in the quoted server.
OpenZFS can also mirror disks, but it manages redundancy together with its filesystem and checksums. A ZFS mirror is not an mdadm array. Compare ZFS separately if filesystem-level integrity, snapshots, and its operating requirements are part of the decision.
Which is faster? Test the workload, not the label
Neither architecture wins every performance test. A controller’s cache and processing can help one workload, while direct access to fast drives can favor a software-managed design in another. Results change with the RAID level, disk type, controller, filesystem, cache policy, read/write mix, queue depth, and whether the array is rebuilding.
A published Dell Technologies comparison tests specified PowerEdge systems and RAID implementations. Its figures are useful for those configurations. They do not predict the result on every NVMe server, controller, or database workload. The report is also published by a controller vendor, so its methods and test conditions should travel with any quoted result.
HDD and SATA or SAS SSD arrays
For a two-disk mirror, modern server CPUs can perform the mirroring work without requiring a separate parity processor. That does not tell you how much application performance changes under load. For RAID 5 or RAID 6, parity updates and rebuild behavior deserve a separate test. A controller with a healthy, protected write-back cache may perform well on some write-heavy patterns, but comparing it with MD under a different cache policy would not isolate the RAID implementation.
NVMe arrays
NVMe drives connect through PCIe. On a multi-drive server, the controller, PCIe lanes, switch, backplane, and drive layout can all affect the usable path. Some RAID products are built for NVMe; others may limit what a set of drives can deliver. Check the actual topology and supported controller rather than assuming that every hardware controller slows NVMe or that software RAID always reaches the sum of the drives’ rated speeds.
A fair benchmark plan
If storage performance will drive the purchase, compare designs with the same server class, drive models and count, RAID level, filesystem, OS, and application workload. Record controller and firmware versions, write-cache mode and protection state, MD settings, drive health, block size, queue depth, read/write ratio, test duration, and repeated runs.
Measure sequential throughput, random IOPS, high-percentile latency, and host CPU use. Repeat the workload with a member missing and during a rebuild. A headline throughput number taken from a healthy array says little about service behavior after a drive fails. When a matched test is unavailable, state the uncertainty rather than publishing an invented speed or CPU advantage.
Write cache and power-loss safety
Write-back cache acknowledges a write after it enters the controller’s cache, before it reaches the disks. That can improve some write patterns, but a sudden power loss can strand acknowledged data if the cache lacks working protection. Write-through waits for the underlying storage path and has a different performance profile. The exact guarantee also depends on drives, flush handling, and the application.
Some controller models use a battery or a supercapacitor and flash storage to protect cached writes. Other models have no such module or permit an administrator to force write-back without it. Dell’s controller documentation warns about data-loss risk when write-back is forced without the required protection. Check the current cache policy and protection health, not just the card’s product name.
With software RAID, the OS and individual drives handle the write path. Enterprise SSD power-loss protection, filesystem behavior, and application sync settings still matter. RAID parity consistency, filesystem checksums, and database durability are related issues with different controls. A UPS helps with power events, but it does not prove that acknowledged writers survive every failure.
Recovery after a drive or controller fails
The most useful comparison is often the recovery procedure your team can carry out on a remote server.
| Event | Hardware RAID question | Software RAID question |
| One drive fails | Can the controller identify its serial and bay, alert the team, and rebuild onto a supported replacement? | Can Linux identify the failed member, alert the team, and add the right replacement partition? |
| Controller fails | Is a compatible replacement available, and how is the existing configuration imported? | Can the drives connect directly to a suitable Linux host and the MD array be assembled safely? |
| OS installation fails | Are controller tools and drivers available in rescue media? | Can rescue media assemble the MD array and access its filesystem? |
| Boot drive fails | Will firmware boot the surviving virtual disk path? | Does the surviving drive have a working ESP or BIOS boot path and bootloader? |
| Data is deleted or corrupted | Can an independent backup restore it? | Can an independent backup restore it? |
Both approaches need a way to identify the correct physical drive. A degraded array may continue serving traffic while its margin against another failure has narrowed. Confirm backups before replacement, monitor rebuild progress and media errors, and check the application afterward. Do not assume one approach rebuilds faster without testing the same drives and workload.
Hardware RAID recovery may depend on controller compatibility and the vendor’s foreign-configuration import steps. Software RAID can reduce dependence on that particular controller, but array portability depends on disk access, metadata, Linux support, and careful assembly. The Hetzner software RAID guide et OVHcloud hardware RAID guide show how much operational detail sits behind the word “RAID.”
Booting from the surviving disk needs its own test
A mirrored root filesystem does not prove a Linux server can boot after one drive disappears. On UEFI systems, the EFI System Partition and firmware boot entries require a plan for each intended boot disk. On legacy BIOS systems, the bootloader must work from each intended disk. A controller-managed virtual disk also needs a supported firmware and rescue path.
The useful acceptance result is a controlled boot test from each remaining disk with remote console access. Provider documentation separates UEFI and BIOS software RAID recovery because the procedures differ.
Monitoring and support on a rented dedicated server
Ask who receives a failed-drive alert and who takes the next action. A hardware controller may expose events through vendor tools or out-of-band management. Linux MD reports array state through the OS, while SMART or NVMe health tools report drive signals. Monitoring must cover the relevant path and reach a working contact. A dashboard that nobody watches does not shorten recovery time.
The provider may replace failed physical hardware while the customer configures the array, restores the OS, or tests backups. Another contract may include some of those tasks. Clarify the split before ordering:
| Task | Question to settle in the quote |
| RAID configuration | Who creates and documents the array and boot layout? |
| Alerting | Who monitors controller or MD events and receives failed-drive notices? |
| Physical replacement | Who identifies the bay, supplies the drive, and performs the swap? |
| Controller failure | Is a compatible unit available, and who imports the existing array? |
| OS rescue | Who provides remote console or rescue media, and who repairs the boot path? |
| Backups | Who runs them, keeps them off-server, and tests restores? |
Do not infer these services from a network uptime target. Confirm the support scope, replacement process, and location for the exact dedicated server.
Compare total operating cost, not only the RAID card
Software RAID may avoid a controller option fee. Hardware RAID may reduce certain administration tasks in a fleet already trained on that controller. Either choice can become costly if the recovery plan needs scarce parts or specialist labor.
Use a 12-month comparison with the same drive count, capacity, backups, and service scope:
12 × (server + controller option + extra drives + management and backup fees)
+ one-time setup + planned spare and recovery costs
Record which fees are known and which require a quote. Include cache-protection maintenance where relevant, compatible controller availability, remote hands, staff time, and backup restore tests. Estimate business downtime only from the organization’s own recovery objectives and operating data. A lower monthly storage price is not proof of a lower total cost.
Choose by workload and recovery requirements
| Workload or requirement | Starting point | Check before deciding |
| Two-drive Linux data mirror | Linux MD RAID 1 can keep disks visible and avoid a dedicated RAID controller | Confirm drive access, alerts, replacement, and backups |
| Two-drive OS mirror | Either approach may work | Prove boot from each disk under the actual BIOS or UEFI layout |
| Database with frequent sync writes | Compare protected controller caching with a suitable software and drive configuration | Test application latency and power-loss behavior, not only bulk throughput |
| Four or more drives with parity | Compare the precise controller and MD layout | Test write load, degraded operation, rebuild, and media error handling |
| Several fast NVMe drives | Inspect direct PCIe and supported RAID paths | Measure the actual topology and workload |
| Virtualization host | Select the storage design supported by the platform and operations team | Check guest workload mix, monitoring, and recovery |
| Media or archive storage | Either design can fit | Weigh capacity, rebuild exposure, and independent backups |
| Fleet with a supported controller standard | Hardware RAID can fit existing tools and spare-stock procedures | Confirm firmware support, cache protection, and controller replacement plan |
An HBA exposing drives individually plus Linux MD is another practical layout where the server needs more drive connections without placing the array behind a controller-created virtual disk. The HBA still requires compatible firmware, drivers, cabling, and monitoring.
Ten questions to ask before ordering
- How many physical drive bays and which drive models does the server include?
- Will the OS see each disk directly, through an HBA, or only as a RAID virtual disk?
- What is the exact controller model and firmware version?
- Which cache policy is active, and is its power protection installed and healthy?
- Does the configuration support the quoted SATA, SAS, or NVMe drives and chosen boot mode?
- Can the OS or management tool report each drive’s serial and health?
- Who configures the array, sends alerts, replaces a failed drive, and watches the rebuild?
- What happens if the RAID controller fails? Is a compatible replacement available?
- Can the team test boot from either intended system drive?
- Where are backups stored, and when was the last restore test?
If you are planning a new machine, review our bare metal server options ou alors request a custom configuration. Share the location, workload, operating system, drive type and count, RAID level, and support tasks you need covered. We can then confirm the available storage design for that specific order.
Frequently asked questions
Is hardware RAID faster than software RAID?
Sometimes, but the controller label alone does not answer this. Drive type, RAID level, cache policy, queue depth, application I/O, and rebuild state change the result. Compare matched systems and publish the test conditions.
Does software RAID use much CPU?
Linux MD uses host resources. The amount depends on RAID level, drive speed, I/O rate, and the server’s CPU. A two-drive mirror and a busy parity array have different demands. Measure CPU use alongside application latency on the intended system.
Should I use mdadm for an NVMe RAID 1 mirror?
It is a reasonable option when Linux sees both drives directly and the team can manage the MD array and boot plan. Check the actual NVMe topology, firmware support, health monitoring, and recovery process before committing production data.
Does a RAID controller protect writes during power loss?
Only if its active write policy and protection hardware provide that protection and the components are healthy. Some controllers operate in write-through mode or permit unprotected write-back. Check the specific model and status.
Can I move a hardware RAID array to another server?
It may be possible with a compatible controller and the vendor’s import process. Do not initialize the disks on the destination. Record the original model and firmware, preserve drive order and serials, and follow the documented recovery procedure.
Can software RAID boot after one drive fails?
It can, but the MD root array is only one part of boot recovery. The surviving disk also needs a working firmware entry, EFI partition or BIOS boot path, bootloader, and initramfs configuration. Test it.
Is ZFS the same as software RAID?
ZFS can provide software-managed redundancy, but it is a filesystem and volume manager with its own pool design and integrity features. An mdadm array is managed by Linux MD and can hold a separate filesystem. Plan and operate them using their own documentation.
Does either type of RAID replace backups?
No. RAID can keep an array available through certain drive failures. It cannot restore a file deleted from both mirror members, undo application corruption, or recover a server lost with all its disks. Keep off-server backups and test restores.
Make the choice you can recover
For a small Linux mirror with direct disk access, software RAID may be the simpler choice. A tested controller with protected cache and an established replacement process may be the better fit for another workload. Before selecting either, document who receives alerts, how a failed part is replaced, whether the server boots after a disk failure, and how the service is restored from backup. Those checks turn a RAID specification into an operating plan.
References and data sources
- Red Hat: Managing RAID
- Linux kernel: MD RAID arrays
- Dell Technologies: Hardware and software RAID comparative study
- Dell: Write-back cache without an energy pack