 تخطي إلى المحتوى




ECC RAM is the safer choice for most production servers because it can correct common single-bit memory errors before an application uses the damaged data. Databases, virtualization hosts, storage servers, financial systems, and long-running compute jobs benefit most. Non-ECC RAM can still suit disposable test systems, low-risk home labs, and workloads that can be rebuilt quickly.
The choice depends on more than the price of the memory modules. The processor, motherboard, firmware, and DIMM type must support ECC as a complete system. Buyers should also consider the value of their data, the cost of downtime, the size of the memory pool, and the number of services that one server supports.
This guide explains how ECC works, where its protection stops, and how to decide which memory type fits your server.
Most Production Servers Should Use ECC RAM
Choose ECC RAM when a wrong value, corrupted record, failed job, or server restart could affect customers or business operations. ECC is strongly recommended for database servers, VM hosts, ZFS or Ceph storage, in-memory applications, and systems that process valuable data.
Non-ECC RAM can be acceptable when all of the following are true:
- The workload contains no authoritative or irreplaceable data.
- The server can be rebuilt without serious cost.
- A failure affects few users or services.
- Tested backups cover any persistent data.
- The lower platform cost has real value for the project.
ECC reduces one class of hardware risk. It does not replace RAID, checksums, replication, monitoring, or backups.
ECC vs Non-ECC RAM at a Glance
| عامل | ECC RAM | Non-ECC RAM |
|---|---|---|
| Full name | Error-Correcting Code memory | Memory without system-level error correction |
| Single-bit errors | Common SECDED implementations correct them | No ECC layer corrects them |
| Double-bit errors | Common SECDED implementations detect them but do not correct them | No ECC detection at the memory-system level |
| Error reporting | Can report corrected and uncorrected events through firmware, a baseboard management controller, or the operating system | Usually provides no equivalent correction telemetry |
| Data integrity | Reduces the risk of undetected memory corruption | Leaves applications exposed to corrupted memory values |
| Platform support | Requires support from the processor, memory controller, motherboard, and firmware | Supported by most consumer platforms |
| Module choices | May use ECC UDIMM, RDIMM, or LRDIMM, subject to platform rules | Commonly uses unbuffered DIMMs in desktop-class systems |
| Capacity scaling | Server platforms often support larger memory pools through RDIMMs or LRDIMMs | Consumer platforms usually support lower maximum capacities |
| الأداء | Depends on memory speed, timings, channels, ranks, population, and workload | Can offer high clock rates and broad tuning options on consumer systems |
| كلفة | May require a server-class platform as well as different DIMMs | Usually lowers the initial hardware cost |
| Common use | Production servers, databases, virtualization, storage, research, and business systems | Consumer PCs, gaming systems, disposable labs, and low-risk test machines |
Why Memory Errors Matter on a Server
RAM holds active instructions and data for the operating system and every running application. A memory error can change one or more bits while that information is in use. The result depends on what the affected bits represent.
A damaged value might cause an application to stop. It might trigger a kernel panic or an unexpected restart. It can also remain hidden. The server may continue working with an incorrect value and later write that value to a database, file, replica, or backup.
That last case is silent data corruption. A visible crash creates an event that administrators can investigate. Silent corruption can pass through normal processing and appear much later as a damaged index, invalid calculation, altered file, or inconsistent transaction.
Soft Errors and Hard Errors
Memory faults usually fall into two broad groups.
Soft errors are temporary. Electrical noise, voltage changes, radiation, temperature, or another short event can change a stored bit without causing permanent damage to the memory cell. The same location may work normally after the event.
Hard errors come from a repeatable hardware problem. A damaged cell, failing chip, faulty connection, or aging component may cause errors at the same location or on the same DIMM. Corrected-error counts often help operators find these developing faults before the system records an uncorrectable event.
A large Google fleet study published in 2009 found that DRAM errors were more common than earlier laboratory estimates and that hard errors played a major role. The study examined older memory generations and a specific server fleet, so its figures should not be used as a current failure forecast for one modern server. Its lasting lesson is simpler: memory errors occur in real production systems, and error reporting has operational value.
Server Exposure Changes the Risk
A desktop used for a few hours each day and a server with hundreds of gigabytes of RAM running all year do not have the same exposure. Several factors raise the practical cost of a memory fault:
- More installed memory creates more locations where a fault can occur.
- Continuous operation increases exposure time.
- High utilization keeps more data active in memory.
- A virtualization host can pass one hardware fault to many guest systems.
- A database can write an incorrect in-memory value to persistent storage.
- A long compute job can waste hours or days before anyone finds a bad result.
- A shared production service can affect many customers at once.
This does not mean that every large server will suffer memory corruption. It means the possible impact grows as the system carries more data, more workloads, and more business responsibility.
How ECC RAM Works
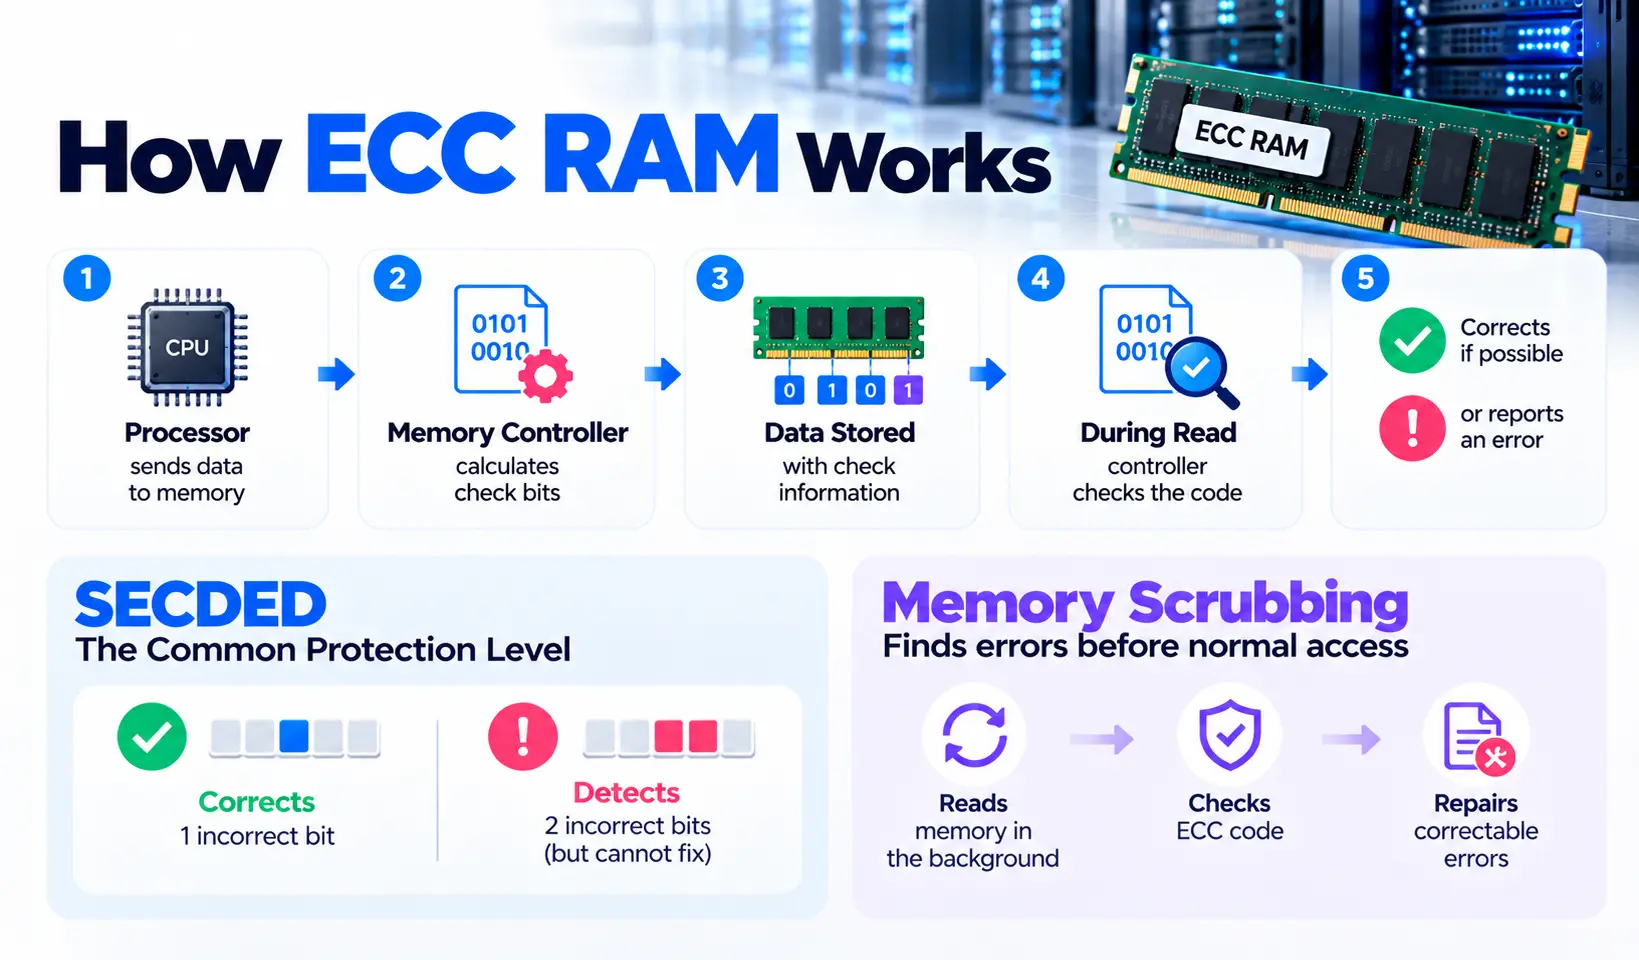
ECC memory stores extra check information with each protected unit of data. When the system writes data to memory, the memory controller calculates a code from the data bits. It stores that code with the data. When the system reads the data, the controller calculates the code again and compares the result.
If the values match, the read continues. If they do not match, the pattern can identify certain errors. The system may correct the data before the processor uses it, record the event, or stop the system when safe correction is not possible.
The basic flow is:
- The processor sends data to memory.
- The memory controller calculates check bits.
- The module stores the data and check information.
- The controller checks the code during a later read.
- The system corrects a supported error or reports an uncorrectable event.
SECDED Explains the Common Protection Level
Many server platforms use Single-Error Correction, Double-Error Detection, known as SECDED. In its common form, SECDED can correct one incorrect bit in a protected memory word. It can detect two incorrect bits in that word but cannot reconstruct the original value with certainty.
The difference between detection and correction matters. A corrected single-bit event can allow the service to continue. A detected double-bit event may cause a machine check, page retirement, process failure, or system stop, depending on the hardware and operating system.
ECC is therefore not a promise that every memory fault can be repaired. It is a defined protection mechanism with correction and detection limits.
Memory Scrubbing Finds Errors Before Normal Access
A memory error can remain in an unused location until software reads that address. Memory scrubbing reduces this risk by reading memory in the background, checking the ECC code, and rewriting corrected data when the platform supports that action.
Server vendors may call this patrol scrub, background scrub, demand scrub, or another platform-specific name. The baseboard management controller, often called the BMC, may also record which DIMM, channel, rank, or address produced an event.
Scrubbing helps in two ways. It can repair a correctable fault before another bit changes in the same protected word. It also produces evidence that administrators can use to schedule maintenance.
Advanced Server Protection Can Go Further
Some server platforms provide stronger Reliability, Availability, and Serviceability features. These may include Chipkill, Single Device Data Correction, memory mirroring, spare ranks, page offlining, and memory-device retirement.
The exact behavior depends on the processor, memory controller, DIMM layout, firmware, and server model. A generic “ECC supported” label does not prove that every advanced feature is present.
What Happens With Non-ECC RAM?
Non-ECC RAM stores and returns data without the same system-level correction process. If a bit changes, the processor may receive the changed value as though it were correct.
Several outcomes are possible:
- The affected value is never used.
- An application produces an incorrect result.
- A process stops with an error.
- The operating system fails.
- A file, database page, archive, or backup receives damaged data.
- A security-sensitive value, such as a permission flag, changes.
- The server behaves unpredictably and the fault is difficult to reproduce.
Non-ECC memory is not defective memory. Most consumer computers operate with it successfully. The difference is the system response when a memory fault does occur. A production server often needs stronger handling because the impact is larger and the workload runs for longer periods.
ECC vs Non-ECC RAM: Main Server Differences
Data Integrity and Availability
ECC can correct common single-bit events before the application sees the changed data. It can also turn some hidden faults into logged hardware events. That reporting gives operators a chance to locate a failing DIMM and replace it during planned maintenance.
Non-ECC systems usually lack this correction and reporting path. A hardware fault may first appear as an application problem, bad output, or unexplained crash. Troubleshooting can take longer because the software team has little evidence that memory caused the event.
الأداء
ECC memory is often described as slower, but the ECC label alone does not predict application performance. Several factors can have a larger effect:
- Memory generation and transfer rate
- Primary and secondary timings
- Number of active memory channels
- Number of DIMMs per channel
- Rank layout
- CPU memory-controller design
- NUMA placement on multi-socket servers
- RDIMM or LRDIMM behavior
- Workload access pattern
A fair comparison requires matched processors, equal capacity, equivalent channel population, aligned memory speeds, the same firmware, and the same workload. A consumer platform with tuned non-ECC memory and a server platform with RDIMMs differ in many ways. A benchmark between them cannot assign the full difference to ECC checking.
For most production buyers, capacity, channel balance, and workload fit matter more than a small theoretical ECC cost. Use measured tests from the exact platform when latency or bandwidth can affect a service target.
Cost and Total Cost of Ownership
The ECC decision includes more than DIMM price. An ECC-capable processor, motherboard, server chassis, remote management system, and supported module class may change the initial cost.
The other side of the calculation includes:
- Downtime and lost transactions
- Damaged or questionable data
- Failed compute jobs
- Engineer time spent tracing random faults
- Emergency maintenance
- Customer impact
- Recovery and verification work
A basic decision model is:
Expected memory-failure cost = estimated incident likelihood × business impact
This formula is a planning aid. It is not a measured forecast. If one bad result or host failure could cost more than the platform difference, ECC is usually the sound choice.
Capacity and Scaling
Large servers often use Registered DIMMs or Load-Reduced DIMMs. RDIMMs buffer command and address signals. LRDIMMs reduce electrical load further. These designs can support more modules and higher total capacities on compatible platforms.
ECC and registered memory describe different properties:
- ECC describes error detection and correction.
- UDIMM describes an unbuffered module.
- RDIMM describes a module with registered command and address signals.
- LRDIMM describes a module designed to reduce electrical loading further.
An ECC UDIMM is both unbuffered and error-correcting. A server RDIMM commonly includes ECC, but “registered” and “ECC” should not be used as interchangeable terms.
Compatibility
An ECC module cannot create ECC support by itself. The following parts must agree:
- Processor and integrated memory controller
- Motherboard and chipset
- BIOS or UEFI firmware
- DDR generation
- Module class, such as ECC UDIMM, RDIMM, or LRDIMM
- Supported capacity and rank layout
- Memory speed and voltage
- Slot population pattern
Some motherboards accept ECC UDIMMs but operate them without correction. Other systems refuse to boot with an unsupported module. DDR4 RDIMMs may fit a DDR4 UDIMM socket physically but remain electrically incompatible. DDR5 uses additional keying differences across some module classes.
Always check the manual and qualified memory list for the exact server model. Physical fit is not proof of functional support.
DDR5 On-Die ECC Is Not Server ECC
DDR5 introduced on-die ECC inside each DRAM chip. The feature corrects certain internal cell errors before data leaves the chip. It helps manufacturers manage denser memory designs and smaller process geometry.
On-die ECC does not provide the same protection as a server ECC memory subsystem. It does not protect every error that can occur between the DRAM chip, module, memory bus, memory controller, and processor. It also lacks the same host-level reporting path used for server error monitoring.
This distinction creates a common buying mistake. A standard consumer DDR5 module may contain on-die ECC while still being sold and operated as non-ECC system memory.
For full server ECC, look for all of these items:
- An ECC-capable processor and memory controller
- A motherboard and firmware that enable correction
- An explicitly supported ECC UDIMM, RDIMM, or LRDIMM
- Firmware or operating-system evidence that ECC is active
- Error counters or hardware logs that administrators can monitor
Kingston describes DDR5 on-die ECC as protection within the DRAM chip and states that it does not correct errors outside the chip or on the bus. Synopsys also separates on-die ECC from side-band ECC used for broader server memory protection.
Does Your Server Need ECC RAM?
The workload decides how much memory risk a server can accept.
Production Databases and Transaction Systems
Production database servers should use ECC RAM. Databases hold data pages, indexes, query results, transaction records, and caches in memory. A changed value can produce an incorrect result or reach persistent storage during a write.
Database checksums and transaction controls remain useful, but they do not cover every point where damaged memory can affect processing. ECC adds protection before the database engine uses the value.
Virtualization Hosts and Container Platforms
A virtualization host should use ECC because one hardware fault can affect many guest systems. The host may run databases, web applications, control panels, firewalls, and customer services in the same memory pool.
The business impact is therefore larger than the failure of one disposable application server. ECC reporting also helps administrators distinguish a host hardware problem from separate guest software problems.
The same logic applies to Proxmox VE, VMware ESXi, Hyper-V, KVM, and other shared compute platforms.
ZFS, Ceph, NAS, and Storage Servers
ZFS does not require ECC RAM as a strict software condition. Many home systems run ZFS with non-ECC memory. ECC is still the preferred choice when the storage server holds valuable or hard-to-recreate data.
ZFS checksums can detect and repair many storage-path errors when redundant data is available. ECC addresses a different point in the path. If memory changes data before a new checksum is calculated, the storage stack may accept and store the changed value with a matching checksum.
Ceph, software RAID, hardware RAID, and ordinary filesystems have the same general boundary. Storage protection cannot correct every error that begins in system RAM.
AI, Machine Learning, HPC, and Scientific Workloads
ECC suits long compute jobs and accuracy-sensitive results. A training run, simulation, rendering job, or analytics task may hold a large working set in memory for many hours. One damaged intermediate value can affect later calculations or force a costly rerun.
CPU system memory and GPU memory are separate areas. A server with ECC system RAM may still use a GPU without ECC protection. Buyers should check both specifications when the full compute path needs error correction.
Financial, Healthcare, and Regulated Systems
Systems that process payments, financial records, health information, or regulated business data should use ECC as one part of a larger integrity plan. The plan should also include access control, logging, storage protection, backups, recovery tests, and change management.
ECC alone does not create regulatory compliance. It reduces a specific hardware risk that can affect data accuracy and service availability.
Web, SaaS, Gaming, and Streaming Servers
The answer depends on the role of the server.
ECC is the stronger choice when the system stores user accounts, billing records, application state, permissions, game inventories, or other authoritative data. It also makes sense when one machine serves many users or carries several virtual services.
A replaceable edge cache, temporary transcoding worker, disposable game test instance, or development web node can accept more risk. The deciding factor is whether the workload can recover cleanly without losing data or causing a long outage.
Home Labs and Development Servers
Non-ECC RAM can be reasonable for a home lab built for learning, testing, media playback, or short-lived virtual machines. Lower-cost consumer hardware may allow the owner to buy more capacity or a faster processor.
ECC becomes more valuable when that same machine stores family photos, business files, passwords, backups, or home services that must remain available. A “lab” label does not make irreplaceable data less valuable.
Five Questions That Decide Whether You Need ECC
Use these questions before choosing a server:
- Would a wrong value be worse than a visible crash? ECC can prevent common single-bit faults from becoming hidden errors.
- Does the server hold authoritative or hard-to-recreate data? Database records, customer data, research results, and original files favor ECC.
- Will the server run continuously with a large memory pool? Greater capacity and longer runtime increase exposure.
- Could one host fault affect many workloads? VM hosts and shared storage systems have a high failure impact.
- Would recovery cost more than the ECC-capable platform? Include downtime, staff time, lost work, and customer impact.
| Workload profile | Error impact | Recovery cost | Recommended choice |
|---|---|---|---|
| Production database or payment system | ارتفاع | ارتفاع | ECC |
| Virtualization host with many guests | ارتفاع | ارتفاع | ECC |
| Business NAS or ZFS storage | ارتفاع | Medium to high | ECC |
| Long scientific or AI job | Medium to high | ارتفاع | ECC |
| Production web or SaaS server | Medium to high | Medium to high | ECC |
| Replaceable cache or worker node | Low to medium | منخفض | Depends on fleet design |
| Disposable development server | منخفض | منخفض | Non-ECC can be acceptable |
| Home lab with no unique data | منخفض | منخفض | Non-ECC can be acceptable |
Check ECC Compatibility Before You Order
The word “ECC” on a DIMM listing is only the first check.
Confirm Processor Support
Read the specification for the exact processor model. Do not rely only on a family name. Support can differ across generations, models, chipsets, and market segments.
Server processors such as Intel Xeon and AMD EPYC commonly support ECC, but the supported module class and maximum capacity can vary. Some workstation and desktop processors also support ECC under specific motherboard conditions.
Confirm Motherboard and Firmware Support
Read the server manual and qualified memory list. Check whether the board enables actual correction or merely accepts an ECC-capable module in non-ECC mode.
Review BIOS or UEFI settings for ECC, memory RAS, patrol scrub, spare ranks, mirroring, or error injection. Available settings vary by platform.
Match the DIMM Class
Identify the required module type before purchase:
- ECC UDIMM
- RDIMM
- LRDIMM
- DDR4 or DDR5
- Supported speed
- Supported rank count
- Maximum capacity per slot
Do not mix UDIMMs with RDIMMs. Do not assume that RDIMMs and LRDIMMs can operate together. Follow the server vendor’s population rules when filling memory channels.
A balanced channel layout often provides better bandwidth and more predictable behavior than an uneven arrangement. Populating more DIMMs per channel may also reduce the supported transfer rate.
Ask the Hosting Provider Direct Questions
Before ordering a dedicated server, ask:
- Does this exact configuration use ECC memory?
- Is ECC correction enabled in firmware?
- Does the system use ECC UDIMMs, RDIMMs, or LRDIMMs?
- Which DDR generation and transfer rate are installed?
- Can the BMC report corrected and uncorrected memory errors?
- Does the provider monitor repeated corrected errors?
- What is the DIMM replacement process?
- Can RAM capacity increase without changing module class or reducing channel balance?
Clear answers prevent a buyer from paying for an “ECC-compatible” system that does not use active correction.
How to Confirm ECC Is Active and Monitor Errors
Installed ECC modules do not prove that the full system operates in ECC mode. Check more than one source when possible.
BIOS, UEFI, and BMC
Start with the server firmware or remote management interface. Look for:
- ECC enabled or active status
- Corrected error count
- Uncorrected error count
- DIMM health by slot
- Memory-channel health
- Patrol scrub configuration
- System Event Log entries
Dell iDRAC, HPE iLO, IPMI interfaces, and other BMC platforms can expose this information. The exact menu names depend on the server generation.
لينكس
Linux provides the Error Detection and Correction subsystem, known as EDAC. Depending on the distribution and hardware, administrators can review firmware information, kernel messages, EDAC counters, and RAS events.
Useful tools may include:
sudo dmidecode –type memory
sudo dmesg | grep -i -E ‘edac|ecc|mce|memory error’
sudo ras-mc-ctl –status
sudo ras-mc-ctl –errors
dmidecode reports information supplied through SMBIOS. A label such as “Single-bit ECC” helps, but firmware data can be incomplete. Pair it with BMC status, kernel EDAC output, or rasdaemon records.
Linux kernel documentation identifies correctable errors and uncorrectable errors as primary memory events collected through EDAC. Correctable events do not mean that application data was damaged, but repeated events can point to a developing hardware problem.
خادم ويندوز
Windows Hardware Error Architecture, or WHEA, records hardware error information in Event Viewer. Supported systems can report corrected memory events and fatal machine-check events.
Microsoft also documents Predictive Failure Analysis for ECC memory. On compatible hardware, WHEA can track repeated errors on memory pages and take a page offline after a configured threshold.
Check the Windows System log for WHEA events. Then compare the event with the BMC log and the server vendor’s diagnostic tools.
Hypervisors
For VMware ESXi, Proxmox VE, and Hyper-V, check the physical host. A guest virtual machine usually cannot see the complete DIMM health data.
Use the BMC, host kernel logs, hardware health service, and vendor management tools. Map the reported slot or channel to the physical module before replacement.
Responding to Corrected Errors
One corrected event does not always require immediate replacement. A rising count, repeated errors at the same address, or errors tied to one DIMM needs investigation.
Record:
- Server model and firmware version
- DIMM slot and channel
- Module part number
- Corrected and uncorrected counts
- Error timestamps
- Temperature and power events
- Workload conditions
- Recent hardware changes
Follow the server vendor’s maintenance thresholds. Reseat or replace hardware only under an approved maintenance process. Continue to watch the counters after the change.
ECC Does Not Replace RAID, Checksums, or Backups
Server reliability needs several controls because each one handles a different failure type.
| Protection layer | Main job | What it does not cover |
|---|---|---|
| ECC RAM | Corrects or detects specified memory errors | Deleted files, failed drives, application bugs, or full server loss |
| Filesystem or application checksums | Detects selected changes in stored or transmitted data | Every error that occurs before the checksum is created |
| RAID | Keeps a storage set operating after selected drive failures | Accidental deletion, all corruption, malware, or disaster recovery |
| Replication | Maintains another data or service copy | Bad writes, operator mistakes, or faults copied to the replica |
| Snapshots | Keeps point-in-time states | Independent recovery after loss of the same storage system |
| Backups | Restores data after loss or corruption | Immediate continuity and guaranteed recovery without restore tests |
A production design may combine ECC, memory scrubbing, storage checksums, RAID, replication, off-server backups, monitoring, and restore tests. These controls work together because no single layer covers every failure path.
Choosing an Atal Networks Server With the Right Memory
At Atal Networks, we recommend selecting memory protection and capacity from the workload risk first. A database, virtualization host, or business storage server usually needs ECC and a platform that reports memory health. A temporary development node may place more value on lower initial cost.
Review our bare metal server specifications to size the processor, RAM, storage, and network together. Our server CPU guide can also help you match processor class with memory capacity and workload needs.
Confirm the exact ECC status, DIMM class, capacity, channel layout, and upgrade path for the selected configuration. If you are planning a database, storage cluster, virtualized environment, or high-memory application, discuss the requirements with our infrastructure team before deployment.
الأسئلة الشائعة
Can ECC RAM correct every memory error?
No. Common SECDED memory corrects a single-bit error and detects a double-bit error within a protected word. It cannot correct every multi-bit, address, bus, controller, or device fault. Some server platforms add Chipkill, SDDC, memory mirroring, or sparing for broader protection.
Can ECC RAM work in a non-ECC motherboard?
It depends on the module and platform. Some motherboards will not boot. Some accept an ECC UDIMM but use it without active correction. Check the processor specification, motherboard manual, firmware support, and qualified memory list.
Can I mix ECC and non-ECC RAM?
Avoid mixing them. Many systems reject mixed configurations or disable correction. Server vendors also restrict mixing UDIMMs, RDIMMs, and LRDIMMs. Use one supported module class and follow the documented population rules.
Is ECC RAM slower than non-ECC RAM?
ECC checking can add some work, but application performance depends on the full memory platform. Speed, timings, channel count, ranks, module population, processor design, and workload behavior can matter more. Use matched-system tests for a numeric answer.
Does DDR5 have ECC built in?
DDR5 DRAM includes on-die ECC that protects certain faults inside each memory chip. Standard consumer DDR5 is still non-ECC at the system level. Full server ECC needs a supported processor, motherboard, firmware, and ECC module.
Does ZFS require ECC RAM?
No. ZFS can operate without ECC. ECC is still recommended when the server holds valuable data because it protects against selected memory errors that storage checksums cannot prevent at every stage.
Does a home server need ECC RAM?
A disposable home lab can use non-ECC memory. A home server that stores original photos, business files, credentials, or backups benefits from ECC. Base the choice on data value and recovery cost instead of the “home server” label.
Is registered RAM always ECC?
Registered signaling and ECC are separate properties. Server RDIMMs commonly provide ECC, but “registered” describes buffering on the module. Verify both the module specification and platform support.
How can I tell whether ECC is working?
Check the BIOS or UEFI, BMC hardware status, and operating-system error interfaces. On Linux, review EDAC or rasdaemon data. On Windows Server, review WHEA events. Do not rely on the DIMM label alone.
Does ECC replace RAID or backups?
No. ECC protects selected memory operations. RAID addresses selected drive failures. Backups support recovery after deletion, corruption, malware, or system loss. A production server often needs all three controls.
Final Decision
Use ECC RAM for production databases, virtualization hosts, business storage, regulated workloads, long compute jobs, and systems where incorrect data or downtime has a material cost.
Non-ECC RAM can serve disposable development environments and low-risk home labs when the owner accepts the added memory risk and maintains tested backups for persistent data.
Before ordering, confirm that the processor, motherboard, firmware, and DIMMs support active ECC correction. Then confirm that the operating system or BMC can report memory errors. That verification turns an ECC label into an operational reliability control.
References and Data Sources
- Google Research, DRAM Errors in the Wild: A Large-Scale Field Study
- Linux Kernel Documentation, Error Detection and Correction Devices
- Linux Kernel Documentation, Reliability, Availability and Serviceability
- Microsoft Learn, Predictive Failure Analysis for ECC Memory
- Kingston Technology, DDR5 Memory Standard Overview
- Synopsys, Error Correction Code in DDR Memories