 Skip to content


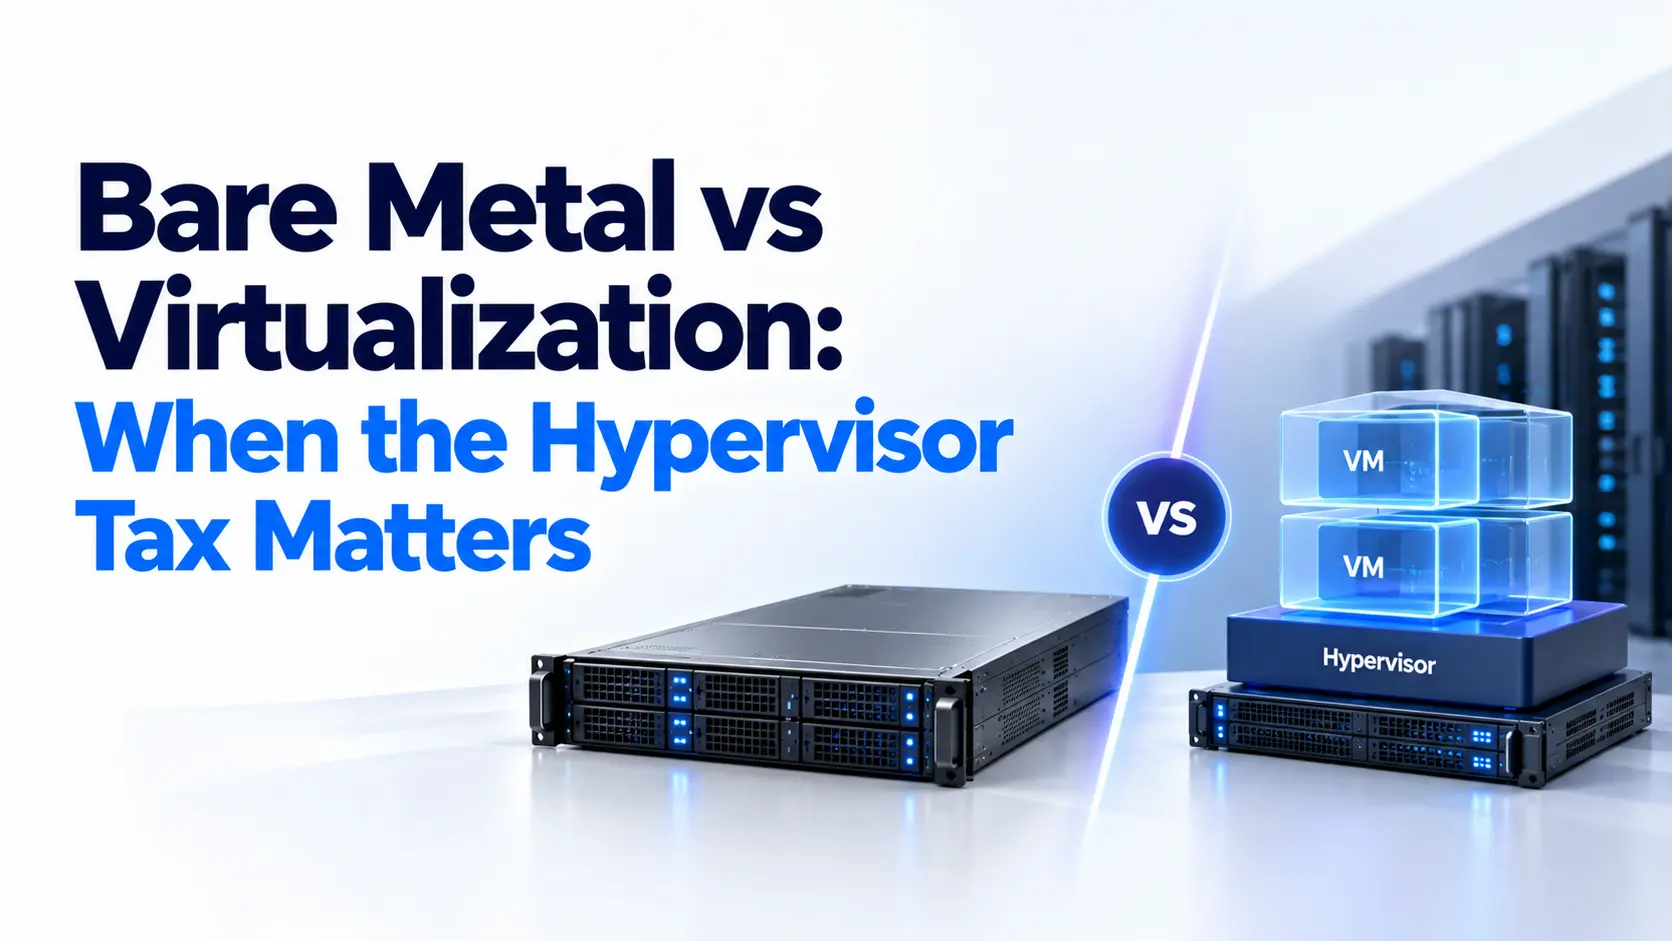
Bare metal runs an operating system directly on physical hardware. Virtualization runs guest operating systems through a hypervisor. The hypervisor tax matters when the extra processing or resource limits affect application response time, throughput, or capacity enough to change your deployment decision. It is not a fixed percentage that applies to every server.
A slower virtual machine does not automatically prove that virtualization caused the problem. Different processors, storage paths, CPU limits, or competing workloads can account for much of the gap.
For a useful bare metal vs virtualization comparison, we need to answer three questions: what is slowing the application, can we correct it, and does the remaining difference justify changing the architecture?
Overview: Bare Metal vs Virtualization
Here, bare-metal deployment means running the application on the physical server’s operating system without a hypervisor underneath that operating system.
| Decision factor | Bare-metal deployment | Virtualized deployment |
|---|---|---|
| Execution | Application and OS run on physical hardware | Application and guest OS run in a VM |
| CPU scheduling | The OS schedules applications | Guest and host scheduling affect execution |
| Memory | The OS manages physical memory | Guest memory maps to resources managed by the host |
| Storage and network | Physical devices or external services | Virtual devices, assigned devices, or external services |
| Isolation | Depends on server tenancy and OS controls | Separate guest environments, with host controls |
| Operations | Physical-server and application procedures | VM lifecycle features, subject to platform support |
| Performance assessment | Measure against the application target | Measure against the same target |
Virtualization and shared tenancy are separate choices. A provider can place VMs on a host dedicated to one customer. You can also rent a bare-metal server and install your own hypervisor.
Our bare-metal server guide explains the underlying hosting model. This article focuses on the performance effect of the execution layer.
Define the Hypervisor Tax Before Measuring It
A hypervisor creates and manages virtual machines. Each VM runs a guest operating system, while the physical system hosting those VMs is the host.
A Type 1 hypervisor operates directly at the hardware layer. A Type 2 hypervisor runs within a host operating system. The phrase “bare-metal hypervisor” describes Type 1 virtualization; it does not mean the workload runs without virtualization.
Containers are different. They isolate processes while sharing a host kernel, and they can run on either physical servers or VMs. Moving to containers does not necessarily remove a hypervisor from the deployment.
The hypervisor tax is an informal name for the extra resource work associated with virtualization. It is not a standardized measurement or a software-license fee.
Before assigning a performance gap to that tax, separate four possible causes:
- Virtualization work: Handling virtual devices, memory mappings, and events that require hypervisor involvement.
- Resource contention: Several workloads competing for processing time, memory bandwidth, or I/O.
- Architecture differences: Different CPUs, disks, network paths, or resource limits.
- Configuration differences: Different drivers, caches, application settings, or operating-system behavior.
Modern virtualization does not carry one universal penalty. In a published 2021 study, AWS found negligible differences between bare-metal and Nitro virtualized instances for the HPC workloads it evaluated. That finding belongs to those workloads and test conditions, not every VM. Source: AWS performance comparison.
CPU Scheduling Can Matter More Than Instruction Execution
Hardware-assisted virtualization allows much guest code to execute directly on the processor. The hypervisor becomes involved for certain operations and events. A VM exit transfers control from guest execution to the hypervisor; it does not occur for every ordinary instruction or every system call.
For buyers, resource allocation often deserves attention before processor mechanics. Eight vCPUs do not automatically equal eight physical cores. Ask how the service maps vCPUs to hardware threads, whether CPU time is capped, and which resources remain shared.
An application can also run out of processing capacity inside a correctly functioning VM. A busy guest does not, by itself, indicate a busy host.
Read CPU Steal Time in Context
On supported Linux guests, steal time helps identify time withheld from guest execution by the virtualization environment. Linux documents the counter as involuntary wait. It is a scheduling signal, not a meter for every form of virtualization overhead. Source: Linux CPU accounting documentation.
Compare it with application latency, CPU use, and the time of the incident. Zero reported steal time does not rule out memory, storage, network contention, or reporting limitations.
Some platforms expose CPU ready time through host monitoring. Check the platform’s definitions and reporting interval before comparing it with Linux steal time.
Memory Placement and Capacity Change the Result
Memory problems can appear even when a server has unused CPU capacity. Separate three requirements: enough RAM to hold the working data, sufficient memory bandwidth, and acceptable access latency.
Virtual machines add a guest-to-host memory mapping. Memory placement also matters on NUMA systems, where a processor can access some memory more directly than memory attached elsewhere in the system.
A VM that spans several memory regions needs suitable CPU and memory placement. A large VM may need multiple NUMA nodes; forcing it into one node can create a different constraint.
Check guest and host memory pressure before changing deployment models. Swapping, a larger-than-expected working set, or an undersized database cache may explain the slowdown.
Huge pages and placement changes can help particular workloads, but they need testing. Red Hat’s tuning documentation treats memory, CPU, and I/O configuration as workload-specific decisions. Source: Red Hat VM performance guidance.
Storage and Network Paths Can Dominate the Comparison
Compare Storage With the Same Durability Requirements
A database using local NVMe on bare metal and another using remote block storage are testing different storage architectures. Their latency gap cannot be assigned entirely to the hypervisor.
Virtual storage can use emulated devices, paravirtualized drivers such as virtio, or supported device assignment. The backing storage, queues, caching, and application behavior all affect results.
Match the read/write pattern and durability settings. Large sequential reads tell you little about a database that waits for small writes to reach persistent storage.
Record the filesystem, write-cache behavior, flush requirements, encryption, and replication. A faster result obtained by weakening persistence is not an equivalent result.
Measure Packet Handling as Well as Bandwidth
A network connection can deliver high bulk throughput yet struggle with many small packets or frequent new connections.
For VPNs, firewalls, proxies, and delivery services, measure packet rate, drops, connection handling, and application delay as well as bandwidth. Virtual switching and host processing may matter, but so can the remote endpoint and network route.
SR-IOV exposes device functions to guests, while PCI passthrough assigns a device to a VM. These options can change the I/O path. Their support and effects on migration, sharing, and recovery depend on the device and platform.
Direct device access still leaves the rest of the application to assess.
Identify Workloads That Notice the Difference
Workload names alone do not decide the deployment. A lightly used database and a write-heavy transaction system have different requirements, even if both use the same software.
| Workload | Measure first | A useful decision question |
|---|---|---|
| Transactional database | Commit latency, p99 response time, successful transactions | Does the VM meet the target with equivalent durability? |
| Game server | Tick processing time and missed deadlines | Do scheduling delays affect play during peak activity? |
| VPN, firewall, or proxy | Packets per second, drops, encryption throughput | Can the network path handle the expected packet mix? |
| Streaming and media | Encoding time, dropped frames, delivery throughput | Is processing or network delivery the limit? |
| AI inference | Time to first token, token rate, request latency | Is the limit accelerator access, memory, batching, or CPU work? |
| Scientific computing | Job time and inter-node communication | Does the tested deployment delay completion? |
| Web applications and CI | Response targets, job duration, usable capacity | Does the measured gap outweigh VM operating benefits? |
The practical concern is often the slowest requests during busy periods. A good average can conceal missed deadlines, stalled transactions, or inconsistent frame delivery.
Use Comparable Tests to Measure the Hypervisor Tax
First decide whether you are testing the virtualization layer or choosing between two hosting products. Those are different experiments.
Test the Layer on Matched Hardware
For a controlled comparison, run the application directly on the physical operating system, then run it inside an isolated VM on the same hardware in a separate test.
Give the application comparable resources. Reserve capacity for host processing, and record those reservations. Keep software, data, security settings, and storage behavior as close as practical.
This estimates the difference introduced by the tested virtualization stack. It does not establish a result for every hypervisor or host configuration.
Test the Service You Will Actually Buy
If you are comparing provider offers, test the configurations available to you. Record different CPUs, storage systems, allocations, and network limits.
Call the result a service comparison if you cannot control those differences. It can still answer the purchasing question, but it cannot prove that the hypervisor caused the entire gap.
Use Three Test Conditions
| Condition | Purpose |
|---|---|
| Direct deployment baseline | Measure the application without the tested hypervisor layer |
| Isolated VM | Estimate the difference with documented virtual resources |
| VM with controlled competing workloads | Assess sensitivity to contention and resource limits |
Run competing workloads only on an authorized test host. If you cannot control the provider’s host, repeat measurements over several periods and state that limitation.
Keep the Method Reproducible
Record hardware, firmware, microcode, kernels, hypervisor, drivers, and application versions. Then keep these conditions consistent:
- Dataset size, request mix, and application configuration.
- CPU allocation, memory, storage persistence, and network destination.
- Warm-up period, run duration, and offered load.
- Security controls and background tasks.
Use a separate load generator and confirm that it can produce the requested traffic. Measure normal demand, expected peaks, and the point where errors or response times become unacceptable.
Record offered requests as well as completed requests. A test that slows its request generation whenever the server stalls can understate the delay users would experience.
Start with the application. Use tools such as sysbench, fio, and iperf3 to investigate a suspected subsystem afterward. Keep disk tests on disposable test data. Bulk network throughput does not measure application response time.
Repeat runs and report variation. One short test is weak evidence for a service that must operate throughout the day.
Read Performance Percentages Correctly
A throughput loss and a runtime increase use different denominators.
Throughput loss relative to bare metal:
(Bare-metal throughput − VM throughput) ÷ Bare-metal throughput × 100
Runtime increase relative to bare metal:
(VM runtime − Bare-metal runtime) ÷ Bare-metal runtime × 100
Consider a hypothetical result of 10,000 completed operations per second on bare metal and 9,500 in a VM. The throughput loss is 5%.
For the same fixed amount of work at those constant rates, the VM takes about 5.26% longer. Neither number describes an application’s tail latency.
Compare Response Times at the Same Load
A p99 response time of 180 milliseconds means 99% of measured requests finish within 180 milliseconds. The remaining requests take longer.
Suppose an application requires p99 response time below 200 milliseconds at its expected peak demand. A hypothetical bare-metal result of 180 milliseconds passes; a VM result of 240 milliseconds fails. That difference matters even if their average throughput looks close.
Compare response times at the same offered load. Then measure how much work each configuration can sustain while staying within the same latency and error limits.
If both options pass with sufficient headroom, a small benchmark gap may have little business value. If one misses a deadline, investigate the cause before approving it.
Tune the VM Before Replacing the Architecture
Start with the limit shown by measurements. Changing several settings at once makes it harder to identify which change helped.
| Observed problem | Investigation or change | Tradeoff to check |
|---|---|---|
| Scheduling delay | CPU caps, allocation, host load, placement | Reserved capacity and service cost |
| Memory pressure | Working set, memory allocation, swapping | Available host memory |
| Poor memory locality | CPU and memory placement | Placement flexibility |
| Slow storage operations | Drivers, queues, backing storage, cache settings | Durability and recovery |
| Packet-processing limit | Virtual NIC, queues, offloads, device assignment | Device and migration support |
Separate guest-level changes from host-level changes. Root access inside a VM does not let you control physical CPU allocation on the host.
CPU pinning sets where a vCPU may execute. It does not, by itself, exclude other VMs or host processes from those CPUs. Libvirt documents separate controls for vCPU placement, emulator threads, I/O threads, and CPU quotas. Check the complete allocation policy before treating a pinned VM as physically isolated. Source: libvirt CPU tuning reference.
Keep security and durability protections consistent during testing. After a material change, recheck both performance and recovery behavior.
Account for the Benefits Virtualization Provides
Virtualization can earn its operating cost even if a direct deployment completes a particular test faster.
VMs let teams separate guest operating systems, create environments from templates, consolidate workloads, and use supported migration or snapshot features. These capabilities can reduce deployment effort and help organize maintenance.
The benefits depend on the platform and design. A VM snapshot is not automatically an independent backup. Several VMs on one physical host still share that host as a failure point. Live migration requires a supported configuration and suitable destination capacity.
Direct deployment also has operating costs: installation, updates, monitoring, replacement procedures, and application recovery. Removing the hypervisor does not remove the operating-system scheduler or prevent applications from competing with one another.
Compare hardware or rental charges, software support and licenses, staff time, backup capacity, recovery resources, and migration work. Check current license terms for the actual deployment instead of assuming that either model always costs less.
Security needs its own review. Neither dedicated hardware nor a VM boundary replaces access controls, patching, protected management interfaces, and tested recovery.
Choose Using Service Targets and Cost per Useful Work
Use the evidence to decide the next step:
| Test result or requirement | Practical next step |
|---|---|
| VM passes normal, peak, and recovery targets | Keep it if the operating model and complete cost fit |
| VM fails because of limits or configuration | Correct the issue or change the service, then re-test |
| A material gap remains in matched tests | Compare direct deployment with migration and operating costs |
| A required hardware feature is unavailable | Evaluate supported bare-metal or device-assignment options |
| Application tiers need different resources | Consider separate placements and include inter-tier network costs |
Calculate cost per completed job or per successful request within the required response time. Include idle headroom and recovery capacity.
A fixed rule such as “move at 70% CPU use” overlooks storage limits, deadline requirements, and the value of VM operations. The better question is whether a configuration can deliver the required work at an acceptable complete cost.
Bare Metal vs Virtualization FAQs
Is bare metal always faster than a virtual machine?
No. Hardware, resource allocation, storage, and software settings affect the result. On matched hardware, virtualization adds work, but the measurable application impact can be small. A better-configured VM can outperform a poorly configured physical deployment.
Does virtualization always reduce performance by 10%?
No. There is no universal 10% penalty. Results depend on the workload, hypervisor, devices, and allocation policy. Use benchmarks with published conditions, then test your application against its own targets.
Is CPU steal time the same as hypervisor overhead?
No. Steal time is a scheduling signal where the platform reports it. It does not measure every cost of memory translation, virtual devices, host processing, or resource contention.
Can a VM with dedicated CPU resources still have overhead?
Yes. Dedicated CPU allocation can reduce scheduling competition, but the virtualization stack remains. Memory placement, storage, networking, and host work can still affect performance.
Can containers run on both bare metal and virtual machines?
Yes. Containers share the kernel of the environment hosting them. Running them inside a VM retains the hypervisor layer and adds a separate guest-kernel boundary between that VM and other guests.
Does GPU passthrough remove every virtualization limit?
No. Assigning a GPU changes device access, but CPU processing, memory, data loading, networking, drivers, and platform support still matter. Test the complete training or inference workflow.
Can we run our own hypervisor on a rented bare-metal server?
Often, provided the hardware, provider terms, software support, and licenses permit it. Confirm virtualization extensions, remote access, storage layout, network requirements, and recovery responsibilities before ordering.
Is a small benchmark difference enough to justify migration?
Only if it changes a service target, capacity requirement, or complete operating cost enough to justify the move. Include migration effort, downtime planning, and the VM features your team would need to replace.
Prepare a Workload Brief for Atal Networks
A useful infrastructure discussion starts with application requirements and measurements. Prepare your application stack, operating system, current configuration, normal and peak demand, and acceptable response times.
Add storage patterns, growth, network traffic, user locations, required hardware features, recovery targets, and management responsibilities. Include any evidence of CPU scheduling delay, memory pressure, or I/O limits.
Review Atal Networks’ bare-metal server options, then confirm the configuration and service scope needed for your workload.
Share your workload and current performance measurements with Atal Networks to discuss suitable infrastructure options.